Showcaseप्रदर्शनी
Some of our work is best explored rather than read. These are interactive sites, visual stories and teaching material built in the lab. More are on the way.हमारे कुछ काम पढ़ने से ज़्यादा खोजकर देखने लायक हैं। ये लैब में बनी इंटरैक्टिव साइटें, दृश्य कहानियाँ और शिक्षण सामग्री हैं। और भी जल्द आ रही हैं।
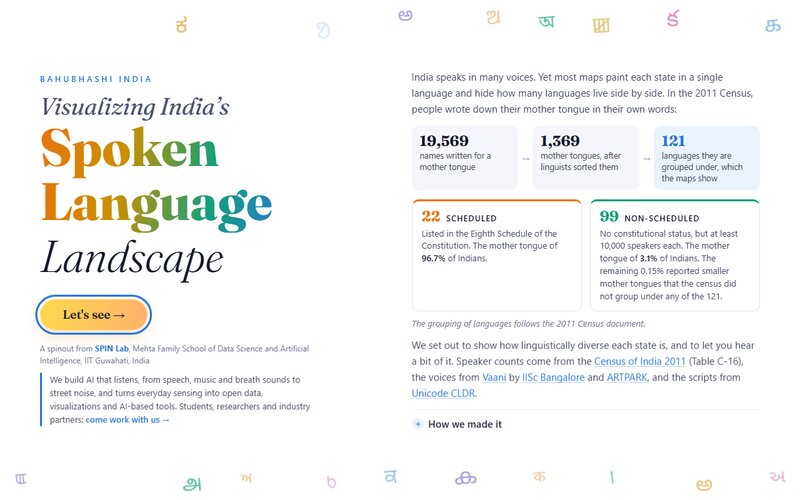
Bahubhashi India ↗
India's spoken-language landscape, state by state. Census 2011 mother tongues drawn as a night sky of languages, scripts and real voices.राज्य-दर-राज्य भारत का भाषाई परिदृश्य। जनगणना 2011 की मातृभाषाएँ, भाषाओं, लिपियों और असली आवाज़ों के रात्रि-आकाश के रूप में।
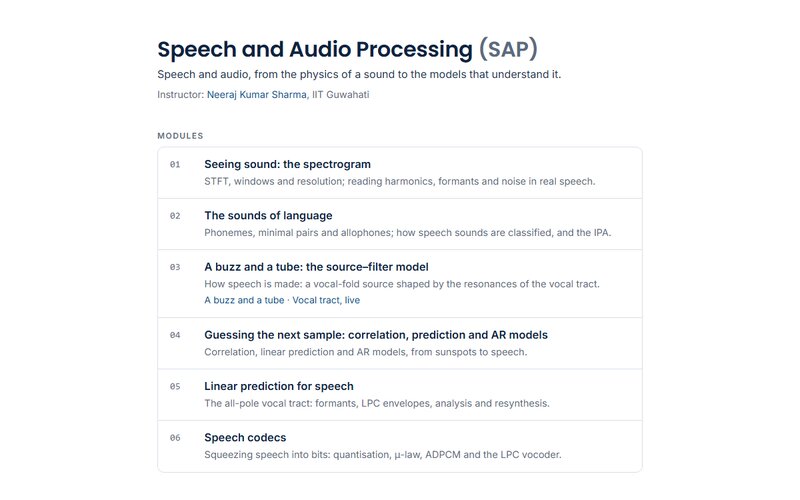
Speech and Audio Processing ↗
An open course, from the physics of a sound to the models that understand it. Spectrograms, source–filter models, linear prediction and codecs, with live demos on Indian-English speech.एक खुला पाठ्यक्रम: ध्वनि की भौतिकी से लेकर उसे समझने वाले मॉडलों तक। स्पेक्ट्रोग्राम, स्रोत-फ़िल्टर मॉडल, लीनियर प्रेडिक्शन और कोडेक, भारतीय-अंग्रेज़ी वाणी पर लाइव डेमो के साथ।
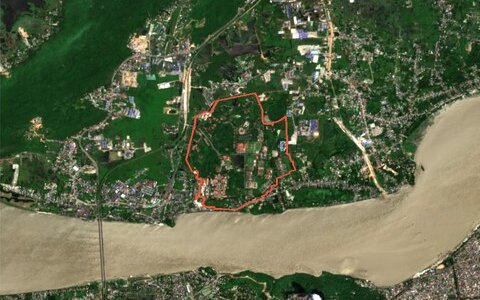
IITG Campus uMap ↗
An unofficial map of IIT Guwahati's hills, lakes and the Brahmaputra, with walking routes, seasons, terrain, satellite greenness and a poster mode.आईआईटी गुवाहाटी की पहाड़ियों, झीलों और ब्रह्मपुत्र का एक अनौपचारिक नक्शा, जिसमें पैदल रास्ते, मौसम, भू-आकृति, उपग्रह से दिखती हरियाली और पोस्टर मोड हैं।
Image contains modified Copernicus Sentinel-2 data (monsoon 2022).
Open datasetsखुले डेटासेट
Coswara
Breathing, cough and speech recordings with COVID-19 symptoms from 2,500+ individuals, recorded 2020–2022.2,500 से अधिक लोगों की साँस, खाँसी और वाणी की रिकॉर्डिंग, कोविड-19 लक्षणों के साथ (2020–2022)।
Paper (Scientific Data, 2023)शोध-पत्र (Scientific Data, 2023) → Get the data →डेटा प्राप्त करें →Boli
A multilingual stuttered-speech dataset from close to 100 people in India, for understanding the stuttering experience.भारत के लगभग 100 लोगों से एकत्रित बहुभाषी हकलाहट-वाणी डेटासेट, हकलाने के अनुभव को समझने के लिए।
Paper (ICASSP 2025)शोध-पत्र (ICASSP 2025) →